Superlog Review (2026): Pricing, Features & Honest Verdict
TLDR
AI-native observability that auto-installs OpenTelemetry, investigates incidents, and posts mergeable fix pull requests to Slack. Best for: Small engineering teams with alert fatigue and no dedicated SRE. Price: Free, then usage-based. Rating: 7.1/10.
What is Superlog?
Superlog is an AI-native observability tool that instruments your code with OpenTelemetry on its own, then investigates production errors and posts a mergeable pull request to Slack when something breaks. Instead of you wiring up tracing and digging through dashboards, a wizard scans your repo, installs proper telemetry, and a daily agent keeps it in sync. The verdict: a genuinely clever take on observability that could save small teams real time, but it is brand new and the public pricing is vague. Best for small engineering teams drowning in alert fatigue. Price: free plan, then usage-based. Rating: 7.1/10.
We found Superlog through its Product Hunt launch, where it pitched itself as “observability that installs itself and fixes the bugs it finds.” It comes out of Y Combinator’s Spring 2026 batch, built by a two-person team. Nicolò Magnante, the CEO, is an ex-BCG consultant and former math olympiad winner who scaled two startups to millions in ARR. Arseniy Shishaev, the CTO, previously worked on data systems at Datadog and co-founded Bluco. So the person building the telemetry engine actually built telemetry engines before. That matters here.
The core idea flips the usual observability story. Normally you install an SDK, manually instrument your services, set up dashboards, and then spend incidents staring at graphs trying to correlate a spike with a deploy. Superlog tries to remove most of that labor. It instruments the code for you, groups errors into incidents, investigates each one with full context, and hands you a PR that fixes it. You review and merge, or you tweak it. The pitch is less “here is a dashboard” and more “here is the fix.”
What are Superlog’s key features?
Instrumentation that installs itself
This is the headline feature and the reason to care. A wizard scans your repositories and installs proper OpenTelemetry instrumentation without you hand-writing spans and traces. For most teams, instrumenting a codebase properly is a multi-week chore that never quite gets finished. Superlog does the boring part and claims to do it correctly. If it works as advertised on real codebases, that alone is worth a trial, because half-instrumented services are the reason so many incidents take hours to debug.
Daily sync so observability does not rot
Instrumentation usually decays. You add telemetry once, ship 200 commits, and six months later your traces have holes everywhere. Superlog runs daily to keep observability in sync with code changes. New endpoints get instrumented, refactors do not silently break your traces, and the coverage stays current without anyone owning it as a chore. This is the kind of unglamorous feature that quietly pays off, and it is the part most homegrown setups never get right.
Incident investigation with full context
When something breaks, Superlog groups related errors into a single incident rather than firing 400 identical alerts. Then it investigates with full context: logs, traces, metrics, and recent deploys all pulled together. So instead of you correlating a 3am error spike with the deploy that caused it, the tool does that correlation up front. For a small team without a dedicated SRE, this is the difference between a fast fix and a ruined evening.
Mergeable fix PRs in Slack
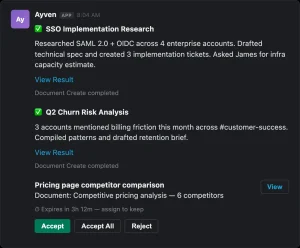
Superlog posts one actionable pull request per incident straight to Slack. You can merge it, modify it, or reject it. This is the boldest claim in the product, and it is also where skepticism is healthy. An auto-generated fix is only as good as the agent behind it, and not every bug has a clean code fix. But framing the output as a reviewable PR rather than an automatic deploy is the right call. You stay in control, and the tool does the legwork of proposing a starting point.
How much does Superlog cost?
Superlog runs on a usage-based model with a free plan, which is good news and the source of my main complaint. The free tier is aimed at side projects and first installs, giving you useful telemetry plus a few investigations with no base fee and no commitment. From there, you pay only for the telemetry you send and the investigations you run. There is no per-seat charge and no flat monthly platform fee, which is a refreshing change from observability tools that bill you a fortune just to log in.
The problem is that the company does not publish hard dollar figures for its paid usage. There are tiers, one for developers shipping fixes from real telemetry weekly and one for teams that want more investigation throughput at a lower marginal price, plus an Enterprise option for higher volumes, custom retention, and SAML. But the actual rates are not on the page at the time of writing. For a tool whose whole pitch is undoing the cost pain of legacy observability, that opacity is a miss. You will need to send real telemetry to see what you actually pay.
Compared to Datadog, where bills routinely surprise teams with hundreds or thousands of dollars a month, Superlog’s “pay for what you send” model is appealing on principle. Just go in with eyes open. Usage-based pricing can be cheap at small scale and expensive at large scale, and without published rates you cannot model it in advance.
It is worth being clear-eyed about the auto-fix claim, because it is the part most likely to over-promise. Not every incident has a tidy code fix. Some bugs are config drift, some are bad data, some are a third-party API falling over, and no agent is going to patch those with a pull request. Where Superlog should shine is the common class of bug that does have a clear code cause: a null that should have been guarded, a timeout that should have been retried, an error path that was never handled. For those, getting a ready-to-review PR with the full incident context attached is a real time saver. Treat the fix PRs as a strong first draft, not gospel, and the feature earns its place.
| Plan | Price | Plan Features | Best For |
|---|---|---|---|
| Free | Free | Useful telemetry plus a few investigations, no base fee, no commitment | Side projects and first installs |
| Developer | Usage-based | Pay for telemetry sent and investigations run; ship fixes from real telemetry weekly | Individual developers and small teams |
| Team | Usage-based | More investigation throughput at a lower marginal price | Growing engineering teams |
| Enterprise | Custom | Higher volumes, custom retention, SAML | Larger orgs with compliance needs |
Who is Superlog best for?
Use Superlog if you are a small engineering team or a solo founder who has never properly instrumented your app and you do not want to spend three weeks doing it. The self-installing telemetry and the free tier make it easy to start, and the incident-to-PR loop is most valuable when you do not have a dedicated ops person. If alert fatigue and slow debugging are eating your week, this is built for you.
Skip Superlog if you already run a mature observability stack with a team that knows it cold, or if you are at a scale where you need battle-tested tooling with predictable enterprise pricing and a long track record. Superlog is two people and a few months old. That is exciting for early adopters and a real risk for anyone who needs guarantees. If you cannot tolerate a young vendor, wait a few cycles and watch how it matures.
Best Superlog alternatives
Sentry is the obvious starting point for error tracking, with a free tier and paid plans from around $26 a month. It is mature, widely trusted, and great at exceptions, but it does not auto-instrument your whole stack or hand you fix PRs the way Superlog aims to.
Datadog is the heavyweight, with deep observability across logs, traces, and metrics. It does almost everything, but it is famous for surprise bills and a steep setup. Superlog is essentially a bet that most teams want a fraction of Datadog’s power with none of its cost anxiety or manual instrumentation.
Honeycomb is the engineer’s favorite for high-cardinality tracing and debugging production with real precision. It has a free tier and usage-based paid plans. It is excellent, but you still drive the investigation. Superlog tries to drive it for you, which is the core philosophical difference.
You could also look at Jam.dev if your pain is more about reproducing reported bugs than instrumenting backend services. It is a different angle on the same goal of shipping fewer bugs. The way to think about all of these is that the incumbents give you powerful tools and expect you to wield them, while Superlog tries to do the wielding for you. Whether that trade is worth it comes down to how much observability expertise sits on your team. Less expertise tilts the case toward Superlog.
Final verdict: Is Superlog worth it?
Superlog is one of the more interesting observability launches we have seen in a while, because it attacks the two parts everyone hates: setting up instrumentation and digging through dashboards during an incident. Auto-installing OpenTelemetry, keeping it current daily, grouping errors into real incidents, and proposing fixes as Slack PRs is a genuinely fresh stack of ideas. The founders have the right background, with a Datadog alum building the telemetry core. For a small team without an SRE, the time savings could be substantial.
But this is an early-stage bet, and you should treat it like one. The team is two people, the product is months old, and the paid pricing is not published, which makes it hard to plan around. Start on the free tier, point it at a real service, and judge two things for yourself: does the auto-instrumentation actually cover your code, and are the fix PRs good enough to merge. If both land, Superlog could replace a lot of manual observability work. If you need a proven, predictable platform today, stick with Sentry or Honeycomb and check back on Superlog in a few months.
Superlog Pros & Cons
What We Like
- Auto-installs proper OpenTelemetry instrumentation without manual span and trace work
- Runs daily to keep observability in sync as the codebase changes
- Groups errors into incidents and investigates with full context: logs, traces, metrics, deploys
- Posts one mergeable fix PR per incident to Slack
- Usage-based pricing with no per-seat or flat platform fee, plus a real free tier
What Could Be Better
- Paid usage rates are not published, so you cannot model cost in advance
- Very young: a two-person team and only months old
- Auto-fix PRs only help for bugs with a clean code cause, not config or data issues
Superlog FAQ
What is Superlog?
Superlog is an AI-native observability tool that automatically instruments your code with OpenTelemetry, investigates production errors with full context, and posts a mergeable pull request to Slack to fix each incident. It is built by a Y Combinator Spring 2026 team.
How much does Superlog cost?
Superlog has a free tier for side projects and uses usage-based pricing after that, charging for the telemetry you send and the investigations you run with no per-seat or flat platform fee. Exact paid rates are not published yet, and Enterprise is custom.
Is Superlog worth it?
For a small team without a dedicated SRE that has never properly instrumented its app, yes, it is worth trying on the free tier. If you need a proven platform with predictable pricing today, the unpublished rates and early-stage risk are reasons to wait.
What are the best Superlog alternatives?
Sentry (from around $26/mo) for error tracking, Datadog for deep all-in-one observability, and Honeycomb for high-cardinality tracing. The difference is that those tools expect you to drive the investigation, while Superlog tries to drive it for you.
Does Superlog offer a free plan?
Yes. The free tier is aimed at side projects and first installs and includes useful telemetry plus a few investigations with no base fee and no commitment.
Who is Superlog best for?
Small engineering teams and solo founders who have never properly instrumented their app and are tired of alert fatigue and slow debugging. It is most valuable when you do not have a dedicated operations person.